I compared unchanged English passages across the checkers, counting only completed attempts. The set contained six samples: four generated pieces, a Lewis Carroll excerpt, and an AI-edited version of that excerpt. Related samples and a lone literary control make this a small comparison, not an accuracy benchmark.
The Clever AI Detector tool completed the set without payment or signup and correctly separated the generated passages from Carroll. That makes it a practical starting point for free checks, not an authority. I couldn’t verify its advertised unlimited use, and its human verdict on the edited excerpt left mixed authorship unresolved.
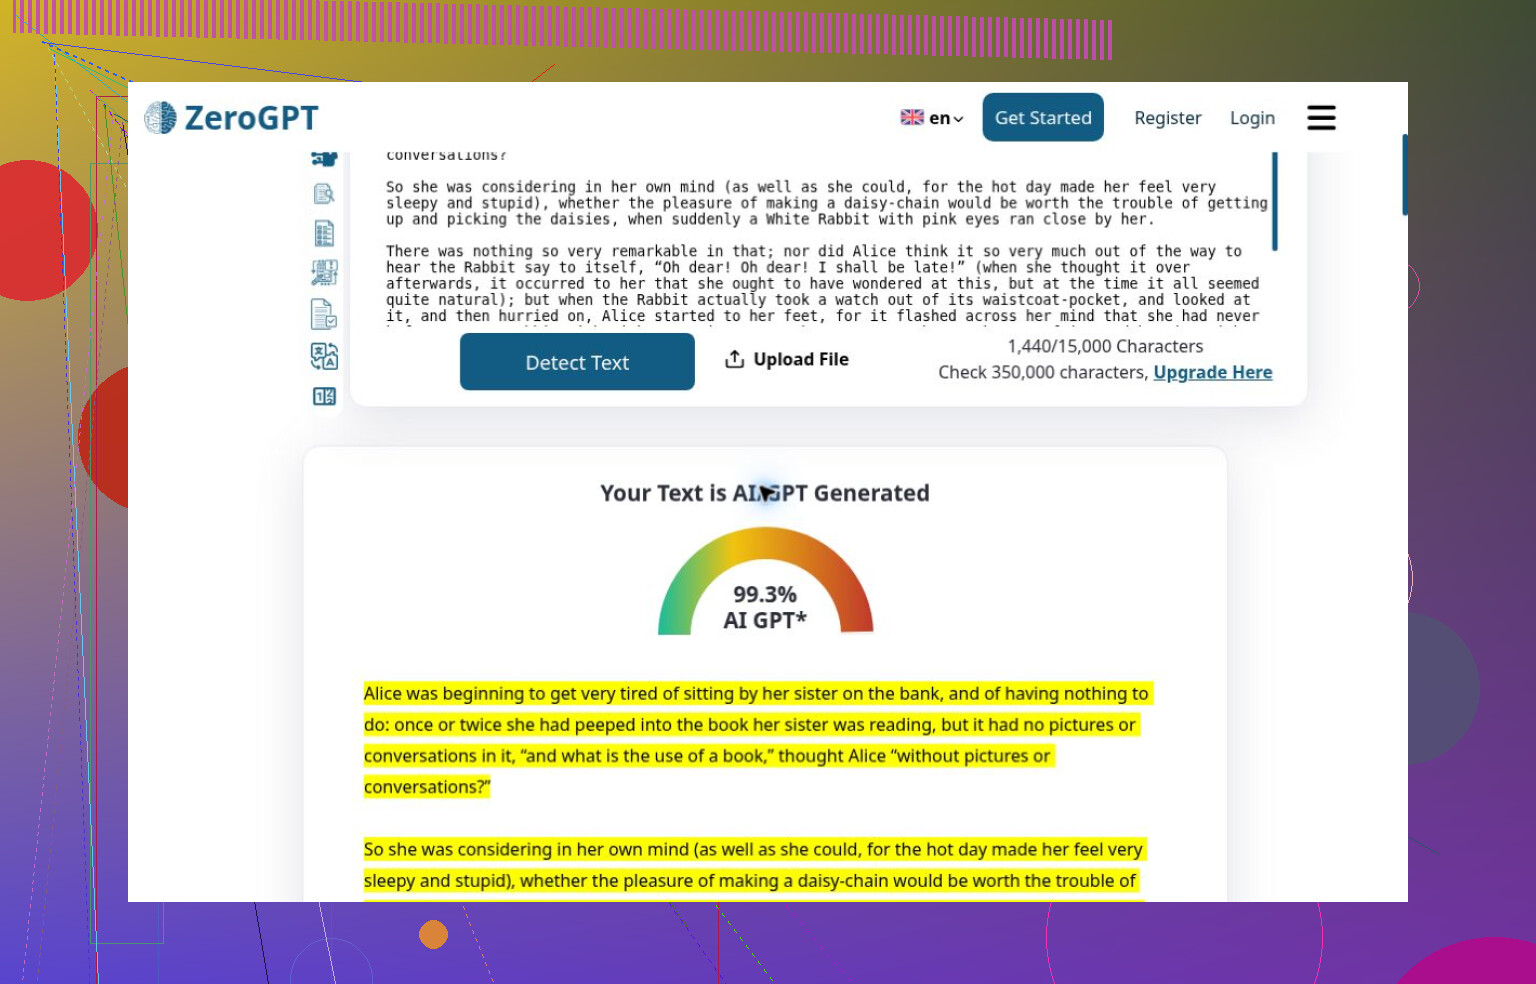
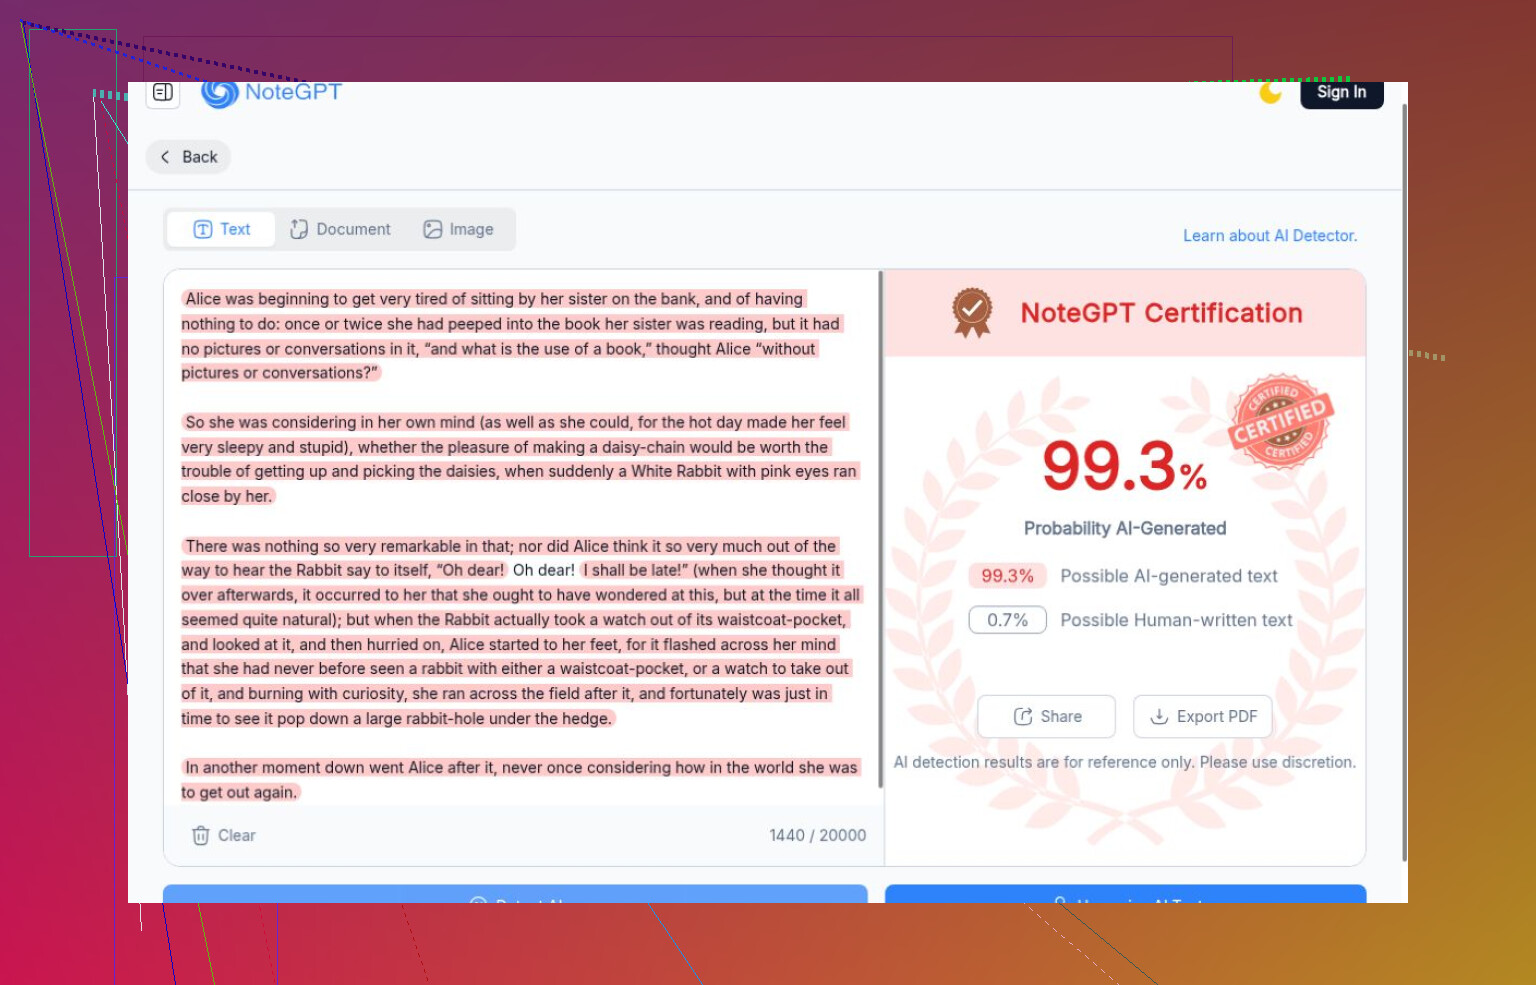
The false accusations bothered me most. ZeroGPT and NoteGPT assigned Carroll their strongest AI scores, at 99.3%. Apparently, being dead doesn’t spare you paperwork.
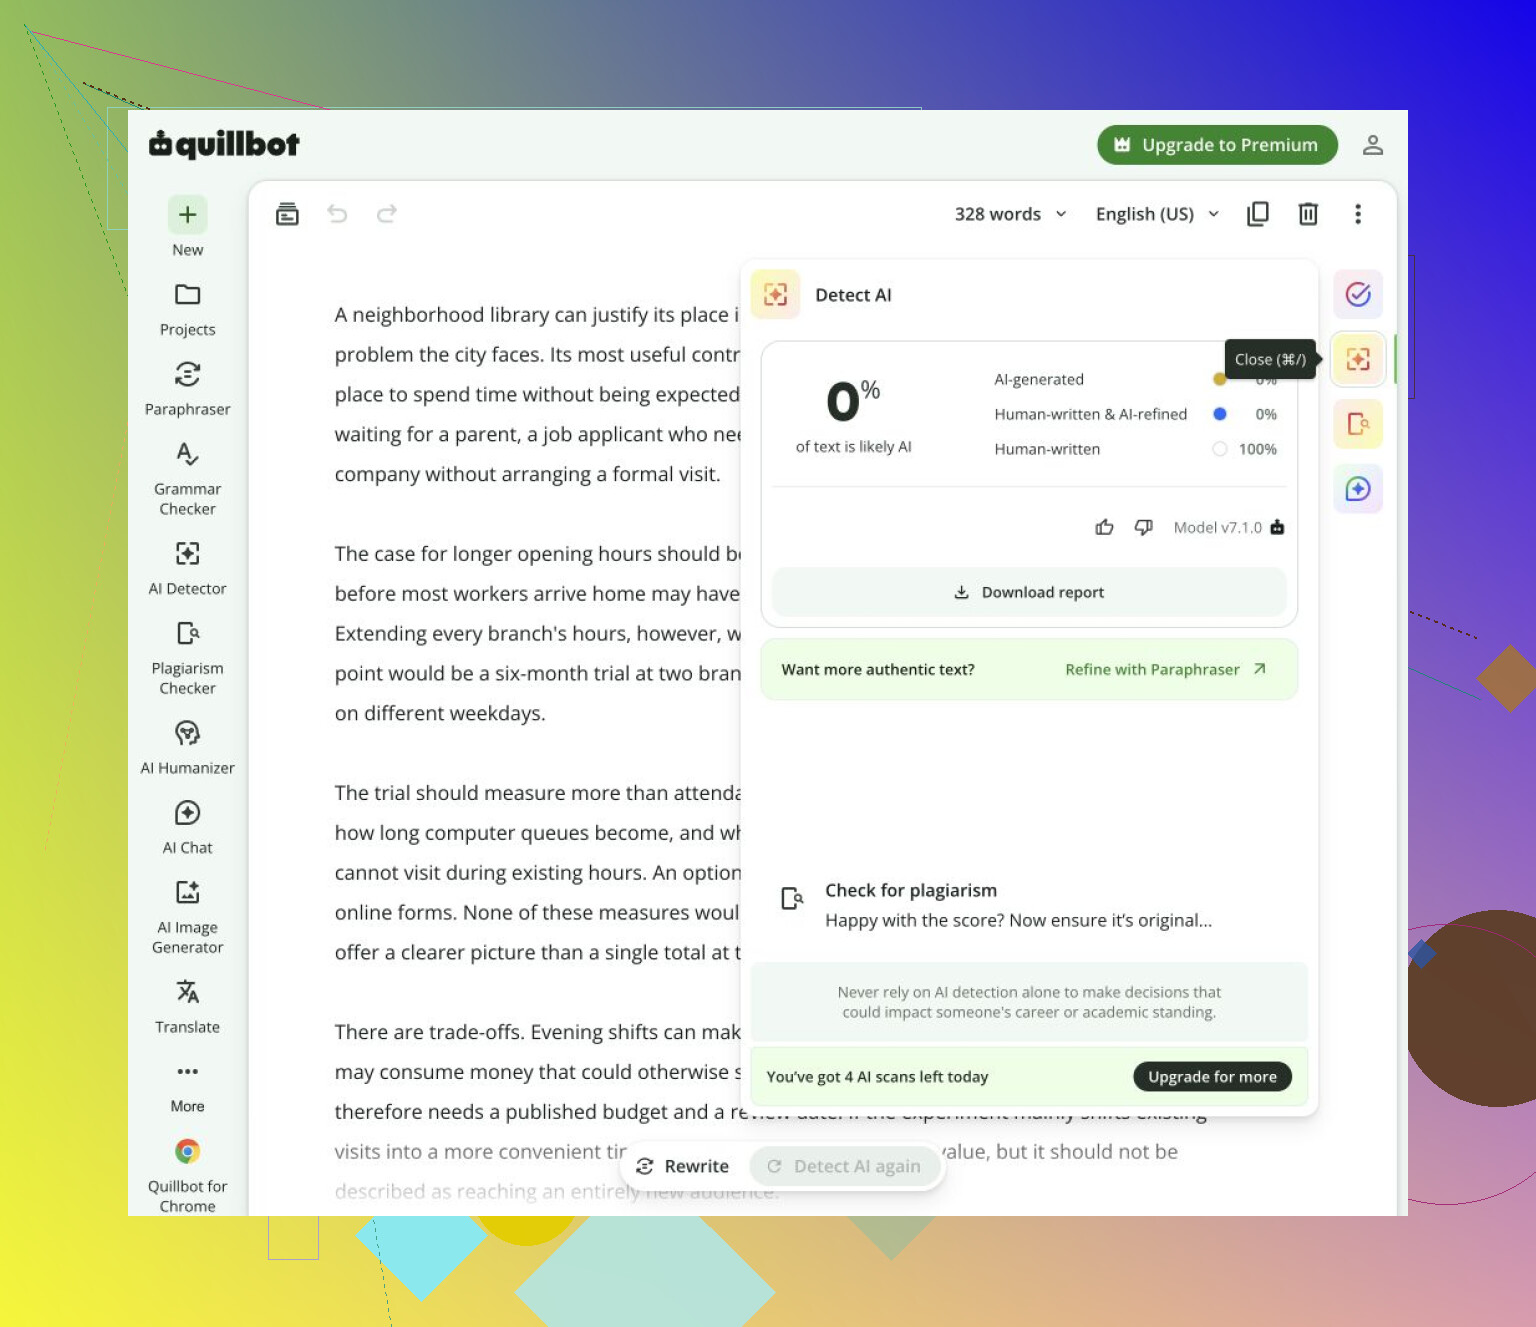
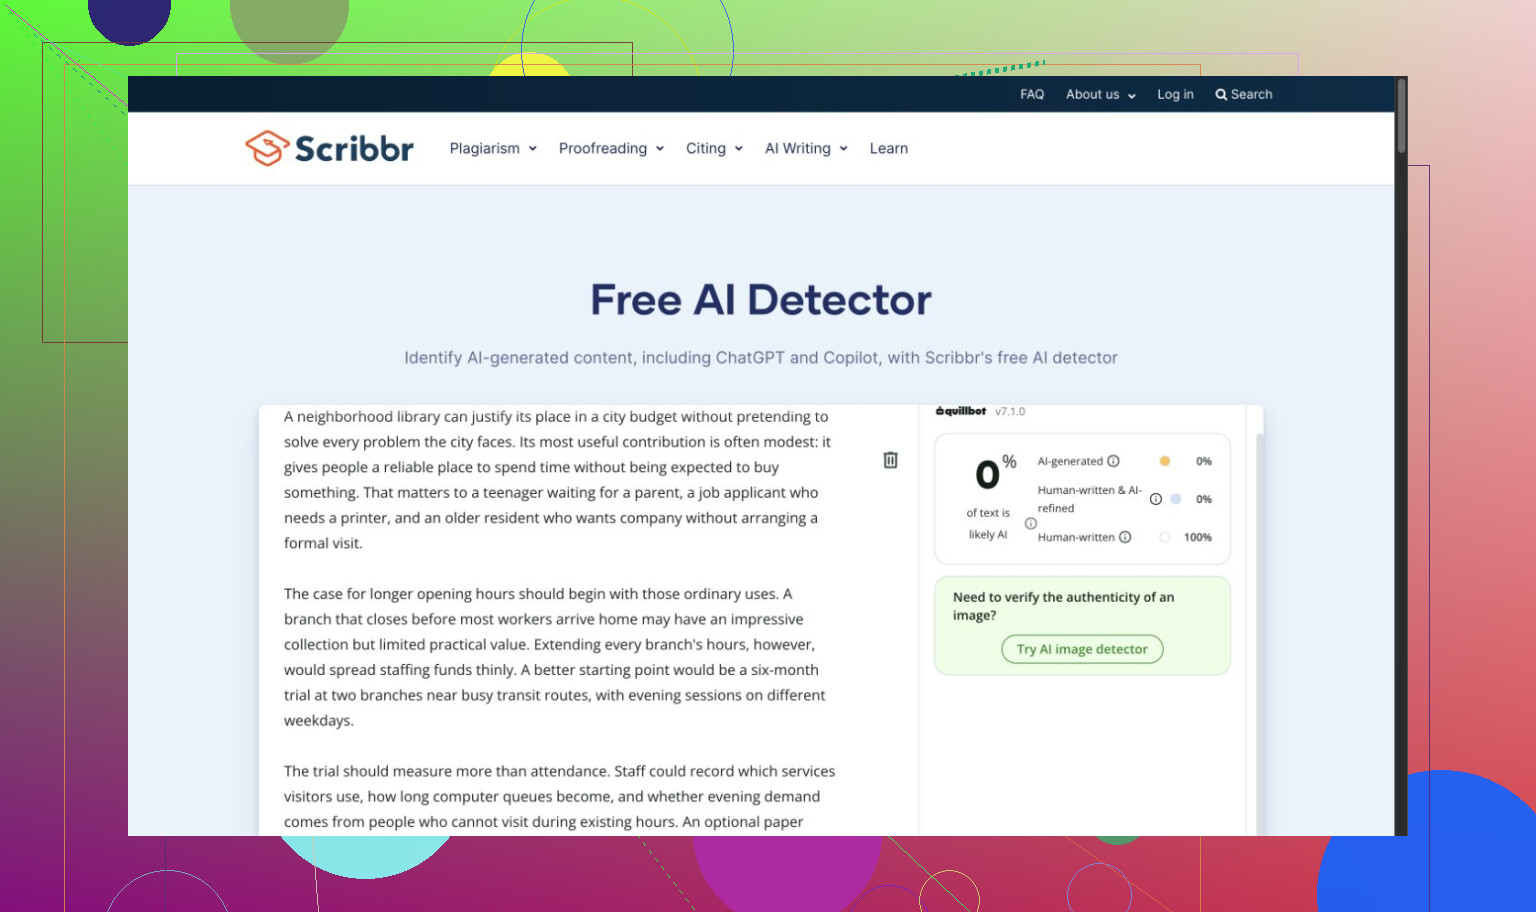
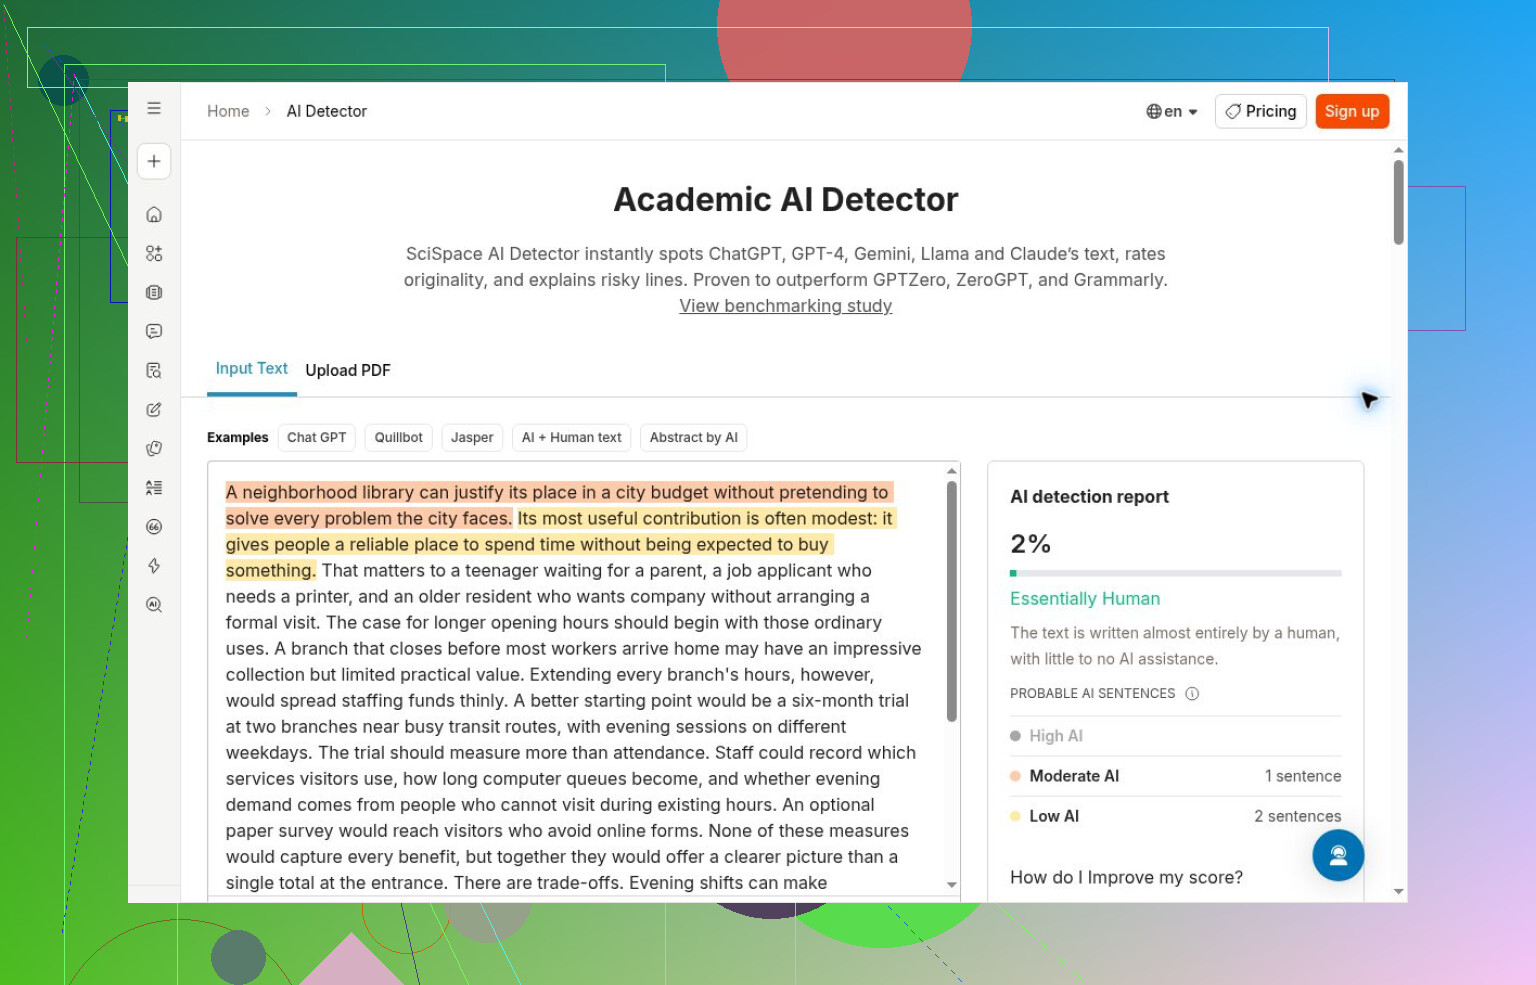
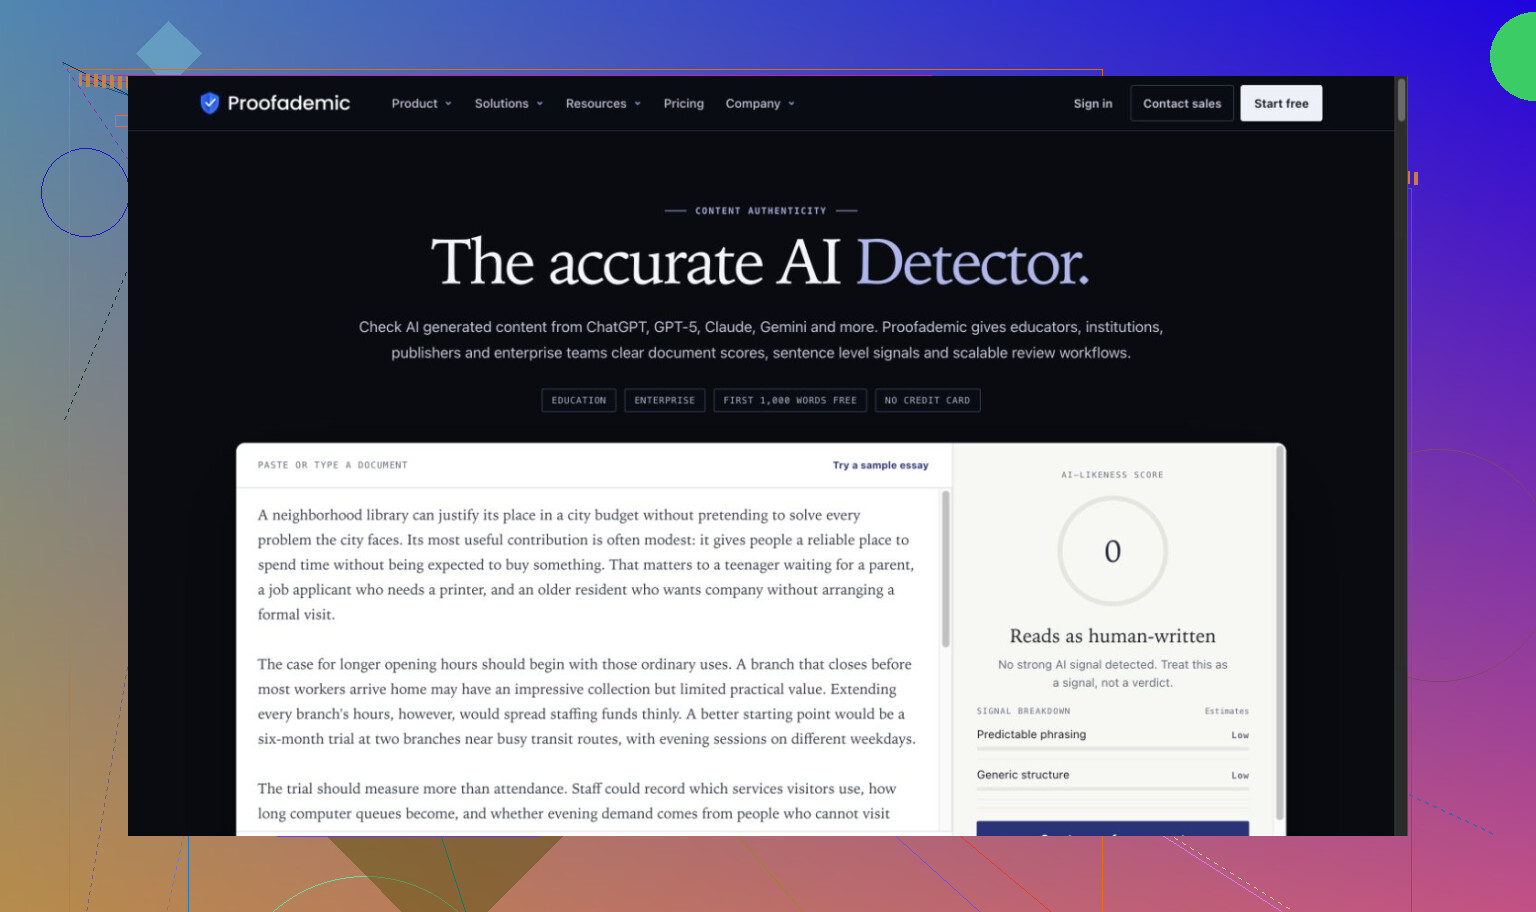
The opposite failure appeared with QuillBot, Scribbr, SciSpace, Proofademic’s public demo, and Surfer: generated writing passed as human. Scribbr’s visible QuillBot branding also stopped me treating them as independent votes.
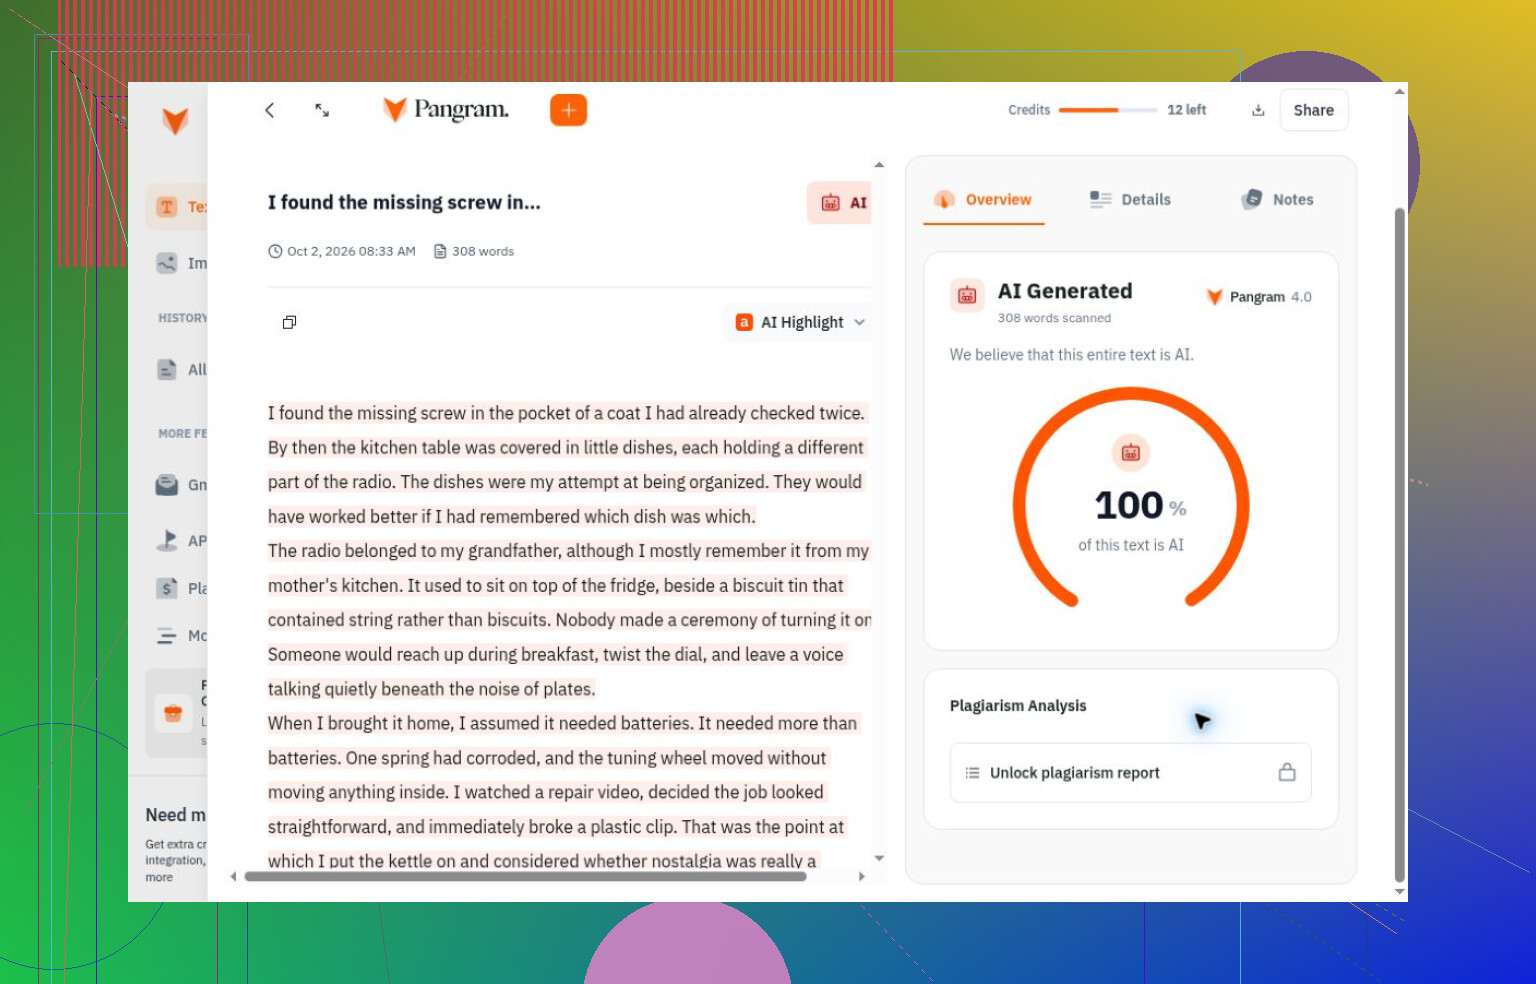
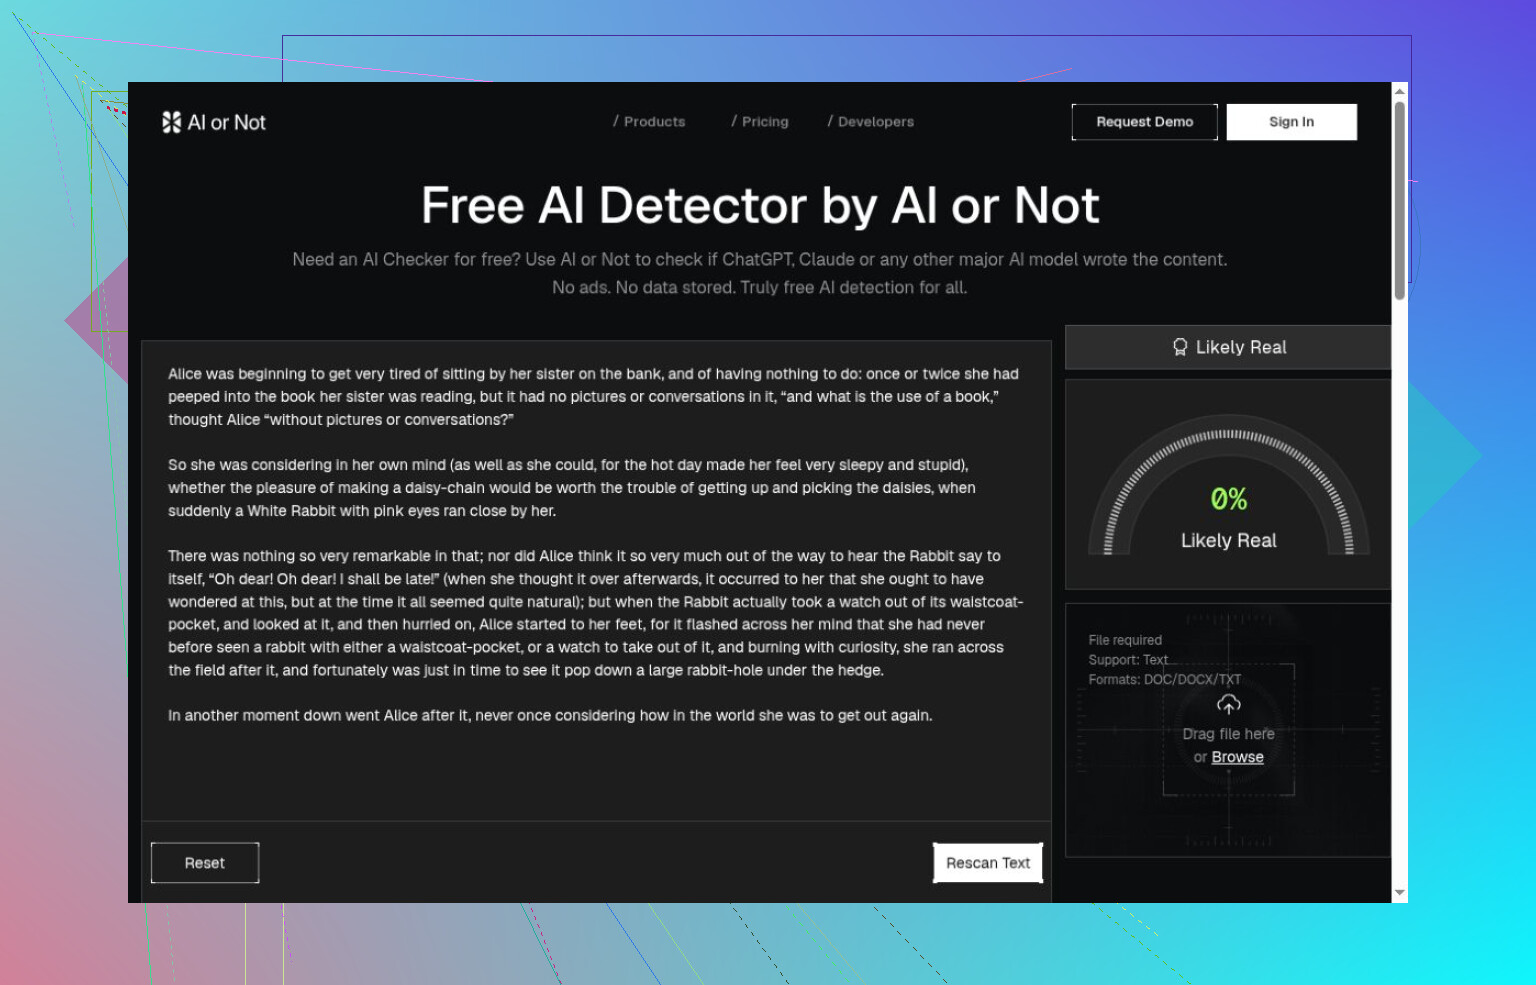
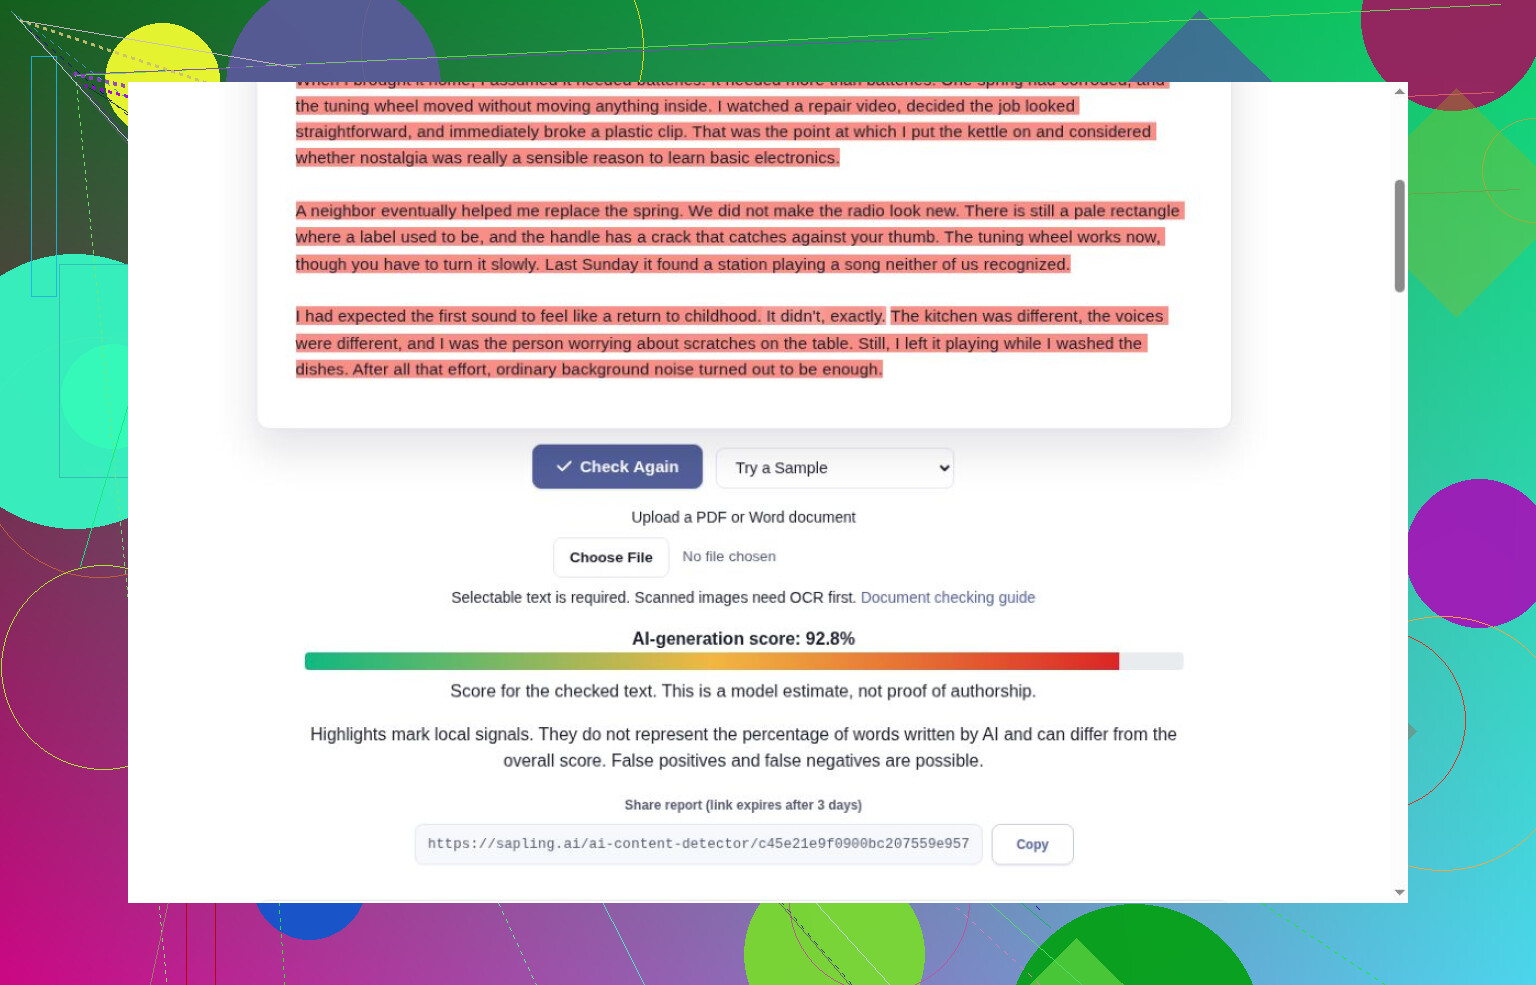
Pangram, Originality.ai, and AI or Not got their narrower completed AI and human checks right. Sapling’s essay result covered truncated text, a qualification worth keeping.
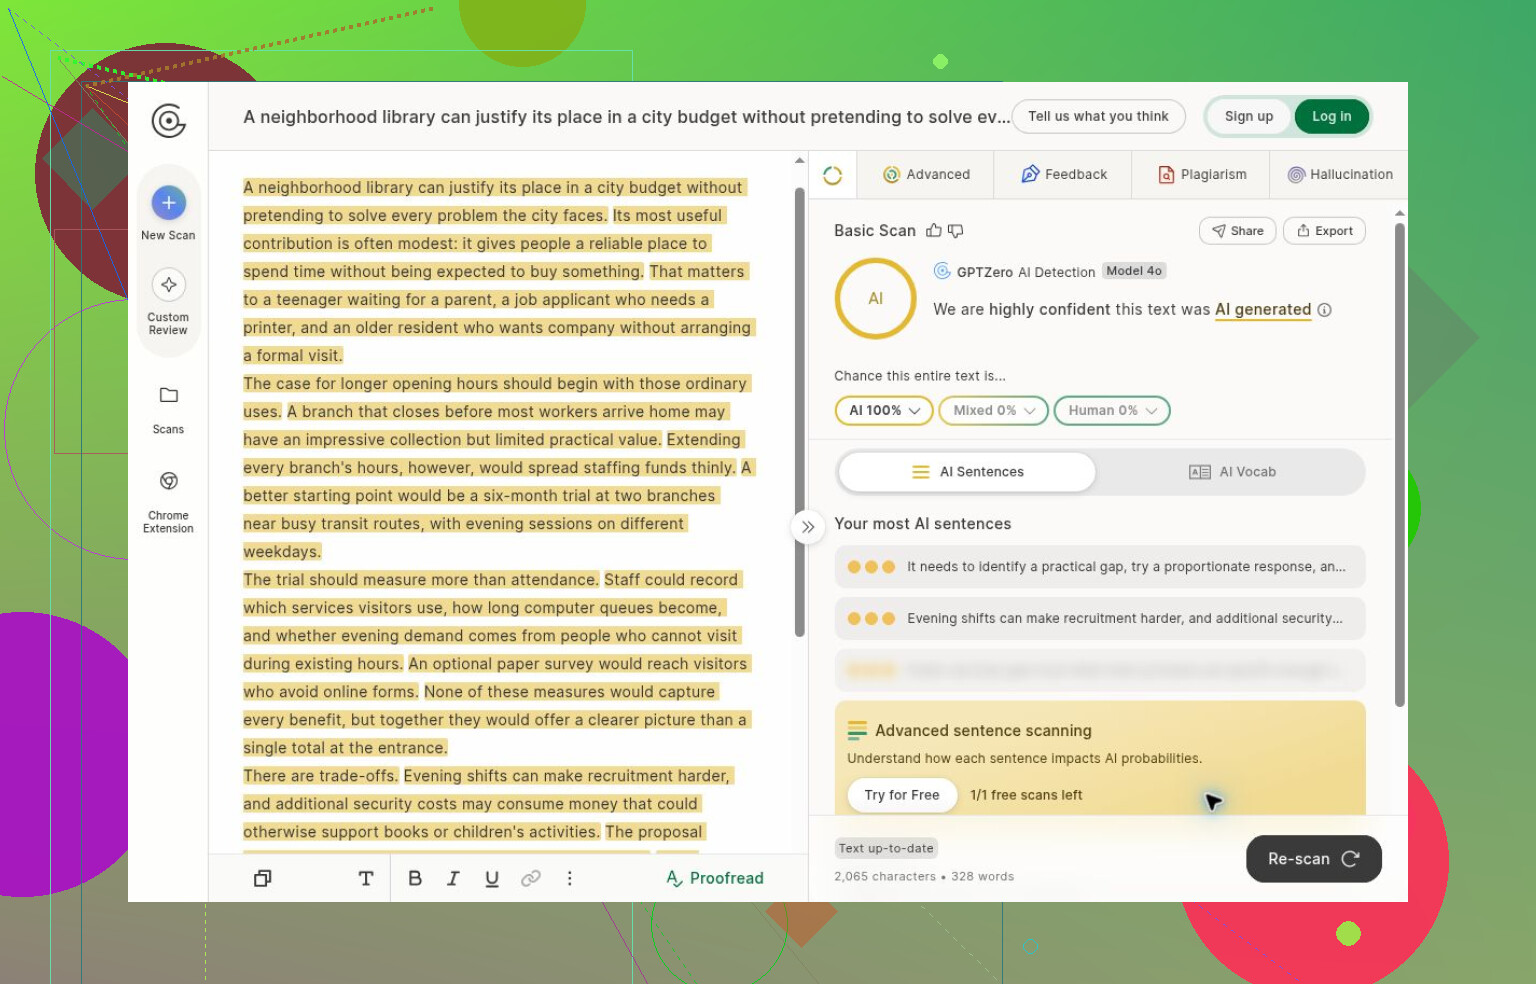
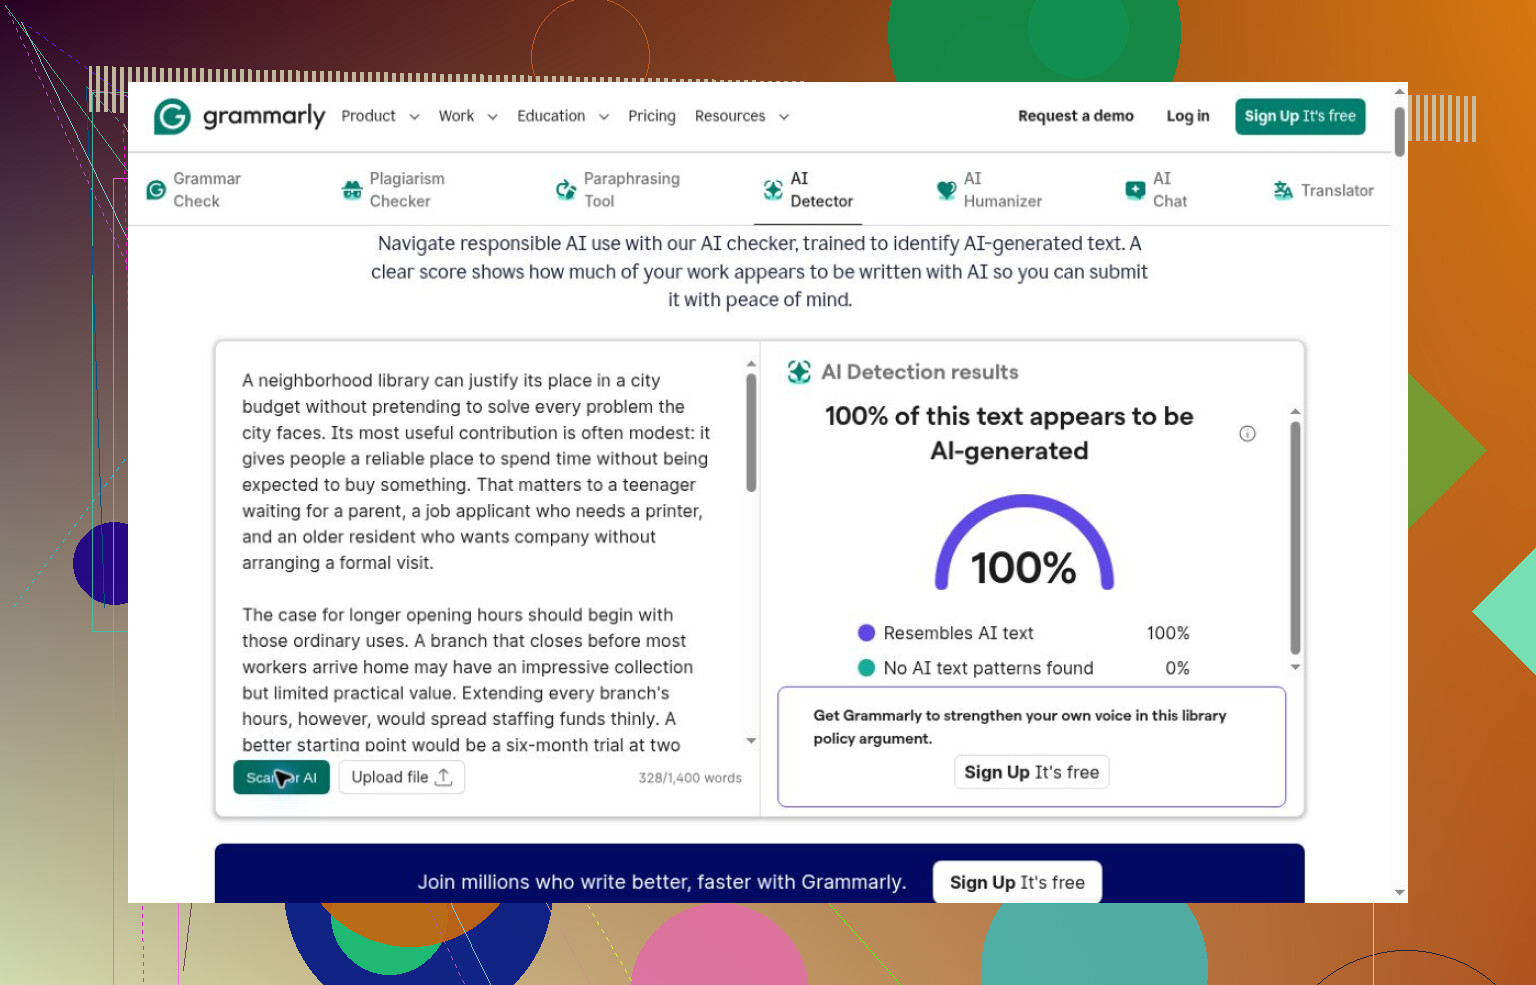
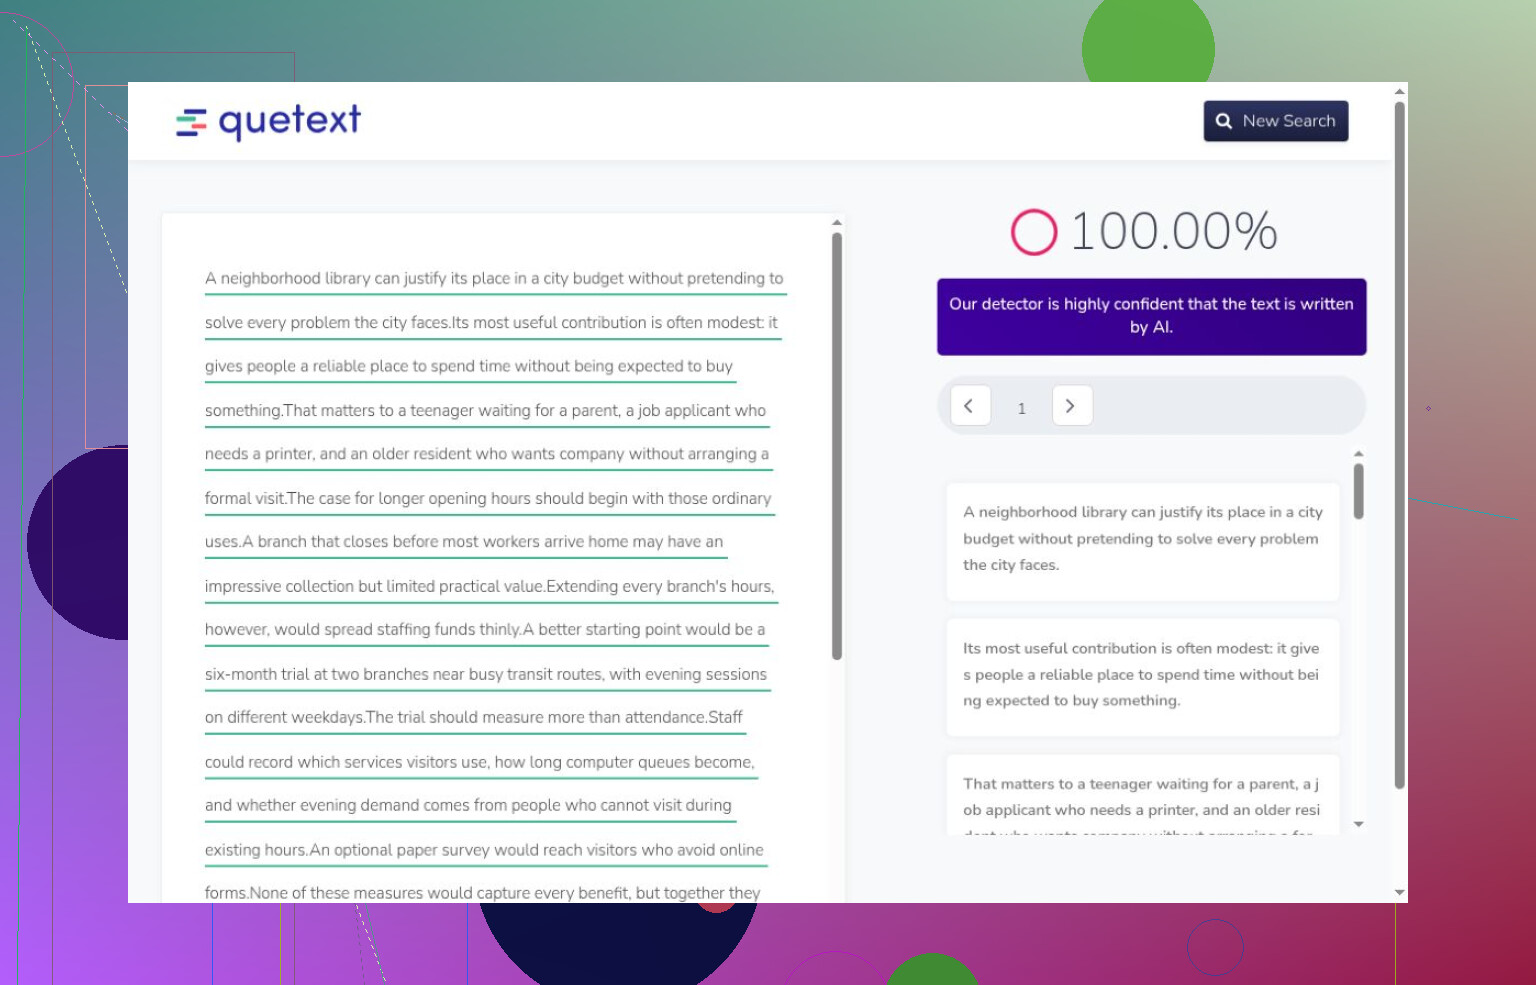
GPTZero, Grammarly, and Quetext caught generated material before signup interrupted testing. Without human checks, I couldn’t assess false positives. GPTZero’s stale displayed score wasn’t another result.
I have no detection verdict for Decopy, Smodin, AI Detector Pro, Winston AI, Copyleaks, or Turnitin. Login barriers, hidden results, applicable-use terms, or institutional access stopped those routes; none establishes detection failure.
Hive, ContentDetector.AI’s Moxby route, and Humanly stayed untested too. I didn’t install their software or configure an API; vendor previews aren’t my results.
I’d investigate disagreements using drafts and sources, not interchangeable-looking percentages. Confidence and estimated AI share mean different things. Broader, repeatable testing across modern human writing, mixed authorship, and languages, with documented false positives, would change how much weight I give these labels.